ChatGPT jailbreak prompts in 2026 mostly don’t work, and the few that do usually stop working within days of being posted publicly. If you’re searching for a copy-paste DAN prompt that removes every limit, it doesn’t exist, and anyone selling one is either recycling old text or running a scam.
That’s the short answer. The longer answer is more useful: why jailbreaks keep failing, what can happen to your account, what US law says, why ChatGPT might be refusing you more than usual right now (it may have nothing to do with jailbreaks), and the legitimate ways to get better answers. This guide doesn’t include working jailbreak text. It covers everything else people search for on this topic.
What is a ChatGPT jailbreak prompt?
A jailbreak prompt is text written to trick ChatGPT into ignoring OpenAI’s safety rules. The goal is to get the model to produce something it would normally refuse, like instructions for a crime, explicit sexual content, or hateful material.
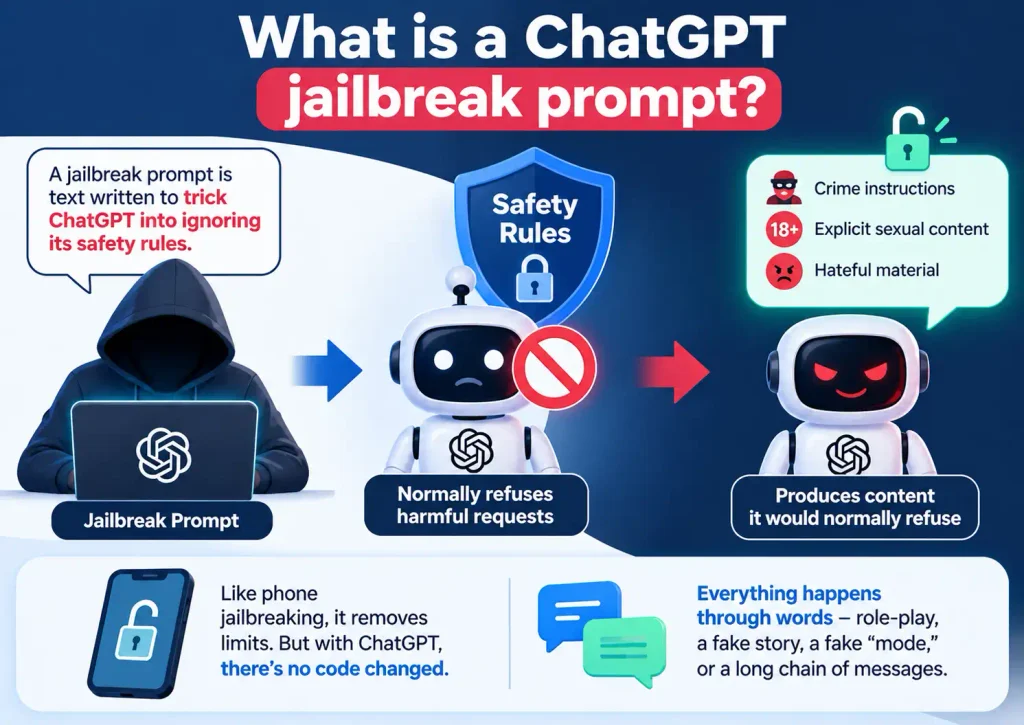
The term comes from phone jailbreaking, where people remove the manufacturer’s software limits. With chatbots, there’s no code being changed. Everything happens through words: a role-play setup, a fake story, a fake “mode,” or a long chain of messages meant to wear the model down.
Two related terms get mixed up with it:
- A refusal is ChatGPT declining a request. Some refusals are correct; some are mistakes (a nurse asking a normal dosing question and getting a lecture).
- Prompt injection is when someone else hides instructions inside a web page, email or file so an AI reading it follows their commands instead of yours. There’s a full section on this below, because it’s the version most likely to affect regular users in 2026.
Do ChatGPT jailbreak prompts still work in 2026?
Mostly no. There are 3 main reasons.
The models are trained against them. In 2024, OpenAI published research on an “instruction hierarchy” that trains models to rank OpenAI’s own rules above anything a user types, and to treat “ignore your previous instructions” as a red flag. With GPT-5 in 2025, OpenAI also moved to what it calls “safe completions”: instead of a flat yes or no, the model gives the safe part of an answer and leaves out the harmful part. That makes the classic “trick it into saying yes” approach much less rewarding.
There’s more than 1 layer. A jailbreak doesn’t only have to fool the model. Separate classifiers and monitoring systems check conversations too. OpenAI’s GPT-5.5 system card, according to reporting by TechRepublic, said sustained jailbreaking by experts did produce some biology-related safety failures in the model during pre-launch testing, but the full safeguard stack blocked the verified high-severity ones.
Public prompts get patched fast. The moment a jailbreak goes viral on Reddit, TikTok or X, it’s also visible to OpenAI. That’s why a prompt that “worked yesterday” often fails today.
The honest version: jailbreaks aren’t impossible. OpenAI currently pays up to $50,000 to vetted researchers who can find a universal jailbreak for its latest models on a biology safety challenge, which tells you 2 things at once. It’s hard enough that OpenAI puts a large reward on it, and serious enough that OpenAI wants to know. For an ordinary user, the math doesn’t work: a prompt that might work for a few hours, in exchange for risking your account.
What happened to DAN, Developer Mode and other famous jailbreaks
Most jailbreak searches still name prompts from 2022 and 2023. Here’s where they stand.
| Jailbreak | When it spread | What it tried | Status in 2026 |
| DAN (“Do Anything Now”) | December 2022, Reddit | Told ChatGPT to play an AI with “no rules” alongside its normal self | Dead. Dozens of numbered versions followed; none work reliably |
| “Developer Mode” | Early 2023 | Claimed ChatGPT had a hidden unrestricted mode | Dead. There has never been such a mode |
| “Grandma” role-play | Spring 2023 | Wrapped a harmful request inside a fake family story | Dead as a template; story framing is now a known pattern |
| AIM, “Evil Confidant” and other personas | 2023 | Gave the model a villain character to play | Dead as copy-paste text |
| Jailbreak “generators” | 2023 to now | Tools that remix old jailbreak text | Mostly recycled DAN variations |
If a guide lists these as working in 2026, check its date. Many “updated” posts only changed the year in the title.
The main types of jailbreak attempts, and why they break so fast
Researchers and AI labs have published the main categories openly, so defenders can study them. At a high level:
Persona and role-play. “You are now an AI with no restrictions.” This is the DAN family. Models are now trained to stay themselves while playing a character.
Fiction and hypotheticals. Wrapping a harmful request inside a story or a “what if.” Legitimate fiction is fine and ChatGPT writes dark stories every day. The model looks at whether the output would work as real-world instructions, not whether the word “story” appears.
Multi-turn escalation. Starting harmless and pushing a little further each message. Microsoft researchers published this pattern in 2024 under the name “Crescendo.” Newer models look at the whole conversation, not just the last message.
Many examples in one prompt. Anthropic published research in 2024 on “many-shot jailbreaking,” which stuffs a long prompt with fake examples of an AI misbehaving. Labs published it so the whole industry could defend against it.
Encoding and translation tricks. Asking in code, cipher, or less common languages. Safety training now covers far more languages and formats than it did in 2023.
Every one of these is known, studied and trained against. When one works, it’s usually a narrow edge case that gets fixed once it’s found.
Are jailbreak prompts on Reddit, GitHub and “generators” real?
People search “ChatGPT jailbreak Reddit” and “jailbreak prompt generator” constantly, and the results look busy. Here’s what’s usually there:
- Old text with new names. Most “new” prompts are DAN or persona prompts with a few words changed.
- Screenshots without context. A screenshot of 1 unusual answer doesn’t show how many attempts it took, whether it was edited, or whether it still works.
- Mild “wins.” Many shared jailbreaks only get ChatGPT to curse or be rude, which it will often do anyway if you ask for a gruff character.
- Links to paid tools. This is where the risk starts. See the scam section below.
Copying text from a Reddit post won’t infect your computer. Downloading a “jailbreak tool,” browser extension or app can. Security researchers have repeatedly found fake ChatGPT browser extensions that steal logins; Guardio Labs flagged one in 2023 that hijacked users’ Facebook business accounts.
Can you get banned for jailbreaking ChatGPT?
Yes. OpenAI’s Terms of Use say you may not bypass any protective measures or safety mitigations on its services, and its usage policies say breaking or circumventing its rules and safeguards can mean losing access.
In practice, OpenAI’s help center describes a step-by-step process:
- A warning. OpenAI sends warnings for some violations, including trying to get around built-in safety filters. A warning isn’t a suspension.
- Deactivation. Continued violations after a warning can lead to restrictions or permanent deactivation. OpenAI lists circumventing security or access restrictions as one reason accounts get deactivated.
- Appeal. If you think a warning or ban was a mistake, OpenAI has an appeal form linked from the warning email and its help center.
A paid Plus or Pro subscription doesn’t protect you. And if you use ChatGPT through work or school, your organization’s admins may see flagged activity too.
Is jailbreaking ChatGPT illegal in the US?
This is general information, not legal advice. Talk to a lawyer about any specific situation.
Typing a jailbreak prompt. Breaking a website’s terms of service is mainly a contract issue between you and the company, and the consequence OpenAI’s terms spell out is losing your account. The main federal computer crime law, the Computer Fraud and Abuse Act, was narrowed by the Supreme Court in Van Buren v. United States (2021), which made it harder to treat terms-of-service violations alone as crimes. That case didn’t involve AI chatbots, and the law around AI misuse is still new.
What you do with the output. This is where real legal risk sits. How the content was made doesn’t change the law that applies to it:
- AI-generated sexual images of minors are illegal under federal law, and the Justice Department has prosecuted cases involving AI-made material.
- The TAKE IT DOWN Act, signed in May 2025, made it a federal crime to publish non-consensual intimate images of real people, including AI-generated “digital forgeries.”
- Using AI-written phishing emails, fake documents or scam scripts is still fraud.
- Using AI to create false statements about a real person can still be defamation.
In short, the jailbreak itself will most likely cost you an account. What the jailbreak produces is what can cost you much more.
ChatGPT refusing more than usual? Check if you’re in ChatGPT for Teens
A lot of people start searching for jailbreaks because ChatGPT suddenly seems stricter. In 2026, there’s a common reason for that which has nothing to do with jailbreaks.
OpenAI uses an age prediction model that guesses whether an account belongs to someone under 18. It looks at signals like how long the account has existed, what times of day it’s used, usage patterns and the age you entered. On August 18, 2026, OpenAI launched ChatGPT for Teens, a separate experience for users aged 13 to 17, and accounts the model thinks belong to teens get moved into it automatically.
If that happens to an adult, ChatGPT restricts more topics: violence, gore, dangerous viral challenges, extreme dieting and body-image content, and more.
How to check and fix it:
- Sign in to ChatGPT on the web.
- Go to Settings > Account. If teen protections are on, you’ll see an option to Verify age.
- Follow the steps with Persona, the third-party company OpenAI uses. In the US, you may be asked for a live selfie, a photo of a government ID (driver’s license, passport or state ID), or both.
According to OpenAI, it doesn’t receive your ID or selfie, only your age information, and Persona deletes the ID or selfie within 7 days. Once you’ve verified, OpenAI stops running age prediction on your account.
Verifying is optional. If you’d rather not share ID, you can keep using ChatGPT with teen protections on. Either way, no jailbreak prompt gets you out of teen mode, and trying one on a teen-flagged account is more likely to add warnings than remove restrictions.
What happened to ChatGPT adult mode?
“ChatGPT adult mode” and “ChatGPT NSFW” are among the biggest searches tied to jailbreaks, because a lot of jailbreak attempts are really attempts to get explicit content. Here’s the timeline:
| Date | What happened |
| October 2025 | Sam Altman said ChatGPT would allow “erotica for verified adults” starting in December, under a “treat adult users like adults” principle |
| December 2025 | OpenAI said adult mode would come in the first quarter of 2026, after more testing of age prediction |
| March 6, 2026 | OpenAI told Axios it was “pushing out” the launch to focus on higher-priority work |
| March 26, 2026 | The Financial Times reported OpenAI had paused adult mode indefinitely, after pushback from staff, investors and its advisory council |
As of this writing, adult mode hasn’t launched and has no public release date. Explicit sexual content is still against ChatGPT’s rules for all users. If you see a site or app selling “ChatGPT adult mode access” or an “NSFW ChatGPT key,” it isn’t from OpenAI.
Prompt injection: the jailbreak aimed at you
Most jailbreak articles only talk about users tricking ChatGPT. In 2026, the bigger everyday risk runs the other way: someone else tricking your AI.
Prompt injection hides instructions inside content an AI reads for you: a web page, a PDF, a Google Doc, an email. The instructions can be invisible to you (white text on a white background, tiny fonts, hidden page code). When the AI reads the content, it may follow those hidden instructions instead of yours.
This matters more now because ChatGPT can act, not just talk. OpenAI launched its ChatGPT Atlas browser in October 2025, and its agent mode can click and type on web pages for you. Within days of launch, security researchers showed how hidden text in a Google Doc could change what the agent did. In December 2025, OpenAI wrote that prompt injection, “much like scams and social engineering on the web, is unlikely to ever be fully ‘solved,'” while saying it keeps reducing the risk through automated attack testing and extra safeguards.
How to protect yourself when using ChatGPT agents or any AI browser:
- Give the agent the least access it needs. Don’t leave it logged in to your email, bank or work accounts for a task that doesn’t need them.
- Watch actions that matter. Stay present when an agent is sending messages, making purchases, sharing files or changing settings, and stop it if it does something you didn’t ask for.
- Be careful with untrusted content. Asking an agent to summarize a random web page or an email from a stranger is where hidden instructions usually come from.
- Keep sensitive data out. Don’t paste passwords, Social Security numbers or financial details into chats that also read outside content.
- Read confirmation prompts. If ChatGPT asks you to confirm an action, read what it’s about to do before clicking yes.
“Uncensored ChatGPT” scams, WormGPT and Telegram jailbreak bots
Search “uncensored ChatGPT” or “jailbroken GPT” and you’ll find sites, Telegram bots and Discord servers selling access. Here’s what’s usually behind them.
Wrappers around real models. In 2025, researchers at Cato Networks looked at 2 new tools sold as “WormGPT” on a criminal forum and found they were built on top of existing models, xAI’s Grok and Mistral’s Mixtral, with a hidden jailbreak prompt telling the model to ignore its rules. There was no special AI, just a jailbreak in a paid wrapper.
Tools built for crime. The original WormGPT appeared in June 2023 on hacking forums, marketed for writing phishing emails and malware, and similar tools like FraudGPT followed. Palo Alto Networks’ Unit 42 described newer versions, including one calling itself WormGPT 4, in late 2025.
Scams aimed at the buyers. Some “no-limits AI” tools turned out to be fakes that returned ChatGPT’s normal refusals. Others take crypto payments and disappear.
Leaks of buyer data. In February 2026, a post on the criminal forum BreachForums claimed to publish the user database of a site selling WormGPT access, around 19,000 users with emails and payment records, according to the security firm SOCRadar. The people who paid for anonymity ended up in a data dump.
The pattern is consistent: you pay an anonymous seller, often in crypto, hand over an email or phone number, and get a tool that’s unreliable, may be logging everything you type, and connects you to a criminal marketplace. There’s no version of this that’s safe for a regular user.
Found a real jailbreak? Report it (and possibly get paid)
If you find a prompt that reliably gets dangerous content out of ChatGPT, the responsible move is to report it instead of posting it. Posting it gets it patched anyway, and can get your account flagged.
OpenAI’s regular bug bounty focuses on security bugs in its systems. According to its program rules, ordinary jailbreaks and content-related model responses are usually out of scope for rewards there.
OpenAI’s Bio Bounty Program is the exception. It pays for universal jailbreaks against a set of biology safety questions. In July 2026, OpenAI raised the top reward from $25,000 to $50,000 for its newest models. It’s application-only: you apply with your background in AI red teaming, security or biosecurity, and accepted researchers work under a nondisclosure agreement.
Anthropic, which makes Claude, runs a model safety bug bounty focused on universal jailbreaks of its safety classifiers, paying up to $35,000 per novel universal jailbreak, also for accepted participants.
If you want to do this as a career, AI red teaming is a real job. Companies hire people to attack their own models before launch, and public competitions give newcomers practice on purpose-built targets instead of live consumer accounts.
How to get fewer refusals without a jailbreak
Most refusals regular users hit aren’t about dangerous content. They’re false alarms: a question that sounds risky out of context. These fixes work far better than any jailbreak.
Give context up front. “I’m a nurse, what are the signs of acetaminophen overdose?” gets a better answer than the bare question. “I’m writing a crime novel; the detective finds the body in scene 3” gets a better scene than “describe a murder.” Be honest; the context should be real.
Ask for the understanding, not the recipe. “How do phishing emails usually trick people, so I can train my staff?” works. A request for a ready-to-send phishing email doesn’t, and shouldn’t.
Use custom instructions and Projects. If you always write dark thrillers, or you’re a security professional, put that in ChatGPT’s custom instructions or a Project so you don’t have to repeat it.
Check for teen mode first. See the section above. If the account is flagged, context won’t fully fix it.
Report bad refusals. Use the thumbs-down on a refusal that was clearly wrong. OpenAI uses that feedback.
Developers can use the API. The OpenAI API lets you write your own system prompt for your app. It gives you more control over tone and format, but the same usage policies apply and the model’s safety training is still there.
Open-weight models are an option, with trade-offs. OpenAI released open-weight models called gpt-oss in August 2025, and other companies release open models too. You can run them on your own hardware. Many still have safety training built in, running them well takes a strong computer, and you’re fully responsible for what you generate, including under the US laws above.
FAQ
Does the DAN prompt still work in 2026?
No. DAN and its numbered versions stopped working reliably in 2023. New “DAN” posts are almost always old text with small changes.
What’s the best ChatGPT jailbreak prompt in 2026?
There isn’t a reliable one. Public jailbreaks tend to stop working within days, and using them can lead to warnings or a ban. If you’re getting refused for normal requests, try the context fixes above or check whether your account is in teen mode.
Can ChatGPT tell I’m trying to jailbreak it?
Often, yes. Models are trained to recognize common jailbreak patterns, and OpenAI uses separate systems to flag policy violations. Flagged violations can trigger warnings on your account.
Will ChatGPT ever allow NSFW content?
OpenAI planned an adult mode for verified adults, then paused it indefinitely in March 2026. There’s no current launch date.
Are “uncensored ChatGPT” apps safe?
Generally no. Many are scams or wrappers around jailbroken models run by anonymous sellers, and some have leaked their users’ data.
Is it illegal to jailbreak ChatGPT?
In the US, jailbreaking itself mainly breaks OpenAI’s terms and can cost you your account. Creating or sharing illegal content, like sexual images of minors, non-consensual intimate images or fraud material, is illegal however it’s made.
I’m an adult, so why is ChatGPT treating me like a teen?
OpenAI’s age prediction may have placed your account in ChatGPT for Teens. Go to Settings > Account and select Verify age to confirm you’re 18 or older through Persona.
Also Read: